-
Price: $0.05495 -0.0616%
-
Market Cap: 8.62B 0.4151%
-
Volume (24h): 395.07M 0%
-
Dominance: 0.4151% 0.4151%
-
Price: $0.05495 -0.0616%

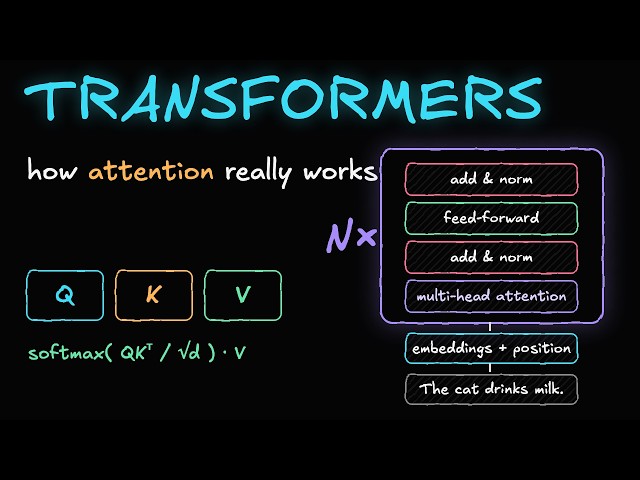
Mixture of experts explained: a 125B LLM on a 32 GB GPU
Release: 2026/10/31 10:53 Reading: 0
Original author:Ignis Inference
Original source:https://www.youtube.com/embed/DrSSAkaLQqM
Mixture of experts explained: how a 125B-parameter LLM runs on a 32 GB GPU at about 100 tokens a second. Each token wakes 10 of 512 experts per layer; the experts wait in host RAM, a VRAM expert cache holds the ones in use, and the price is paid on PCIe. Full write-up: https://gpillon.github.io/ignis/why-ignis/flash-next/ ignis on GitHub: https://github.com/gpillon/ignis (Apache-2.0) Chapters 0:00 125B on a 32 GB card 0:20 512 experts, 10 per token 0:37 Read only what you use 0:52 Make them small 1:11 Where the experts live 1:30 How often the cache hits 1:47 The price: the link 2:08 The right question The numbers in this video Qwen3.8-Flash-Next (125B mixture of experts, 48 layers, 512 routed experts per layer, 10 per token, about 6B active), served by ignis on one RTX 5090 (32 GB) on a PCIe 3.0 x16 host (about 12 GB/s): - Experts stored in a trellis code at 2, 2.5, 3 or 4 bits per expert, 2.5 bits a weight on average with scales: 120.8B expert parameters in 37.7 GB, pinned in host RAM. - One lane, greedy, one prompt repeated, expert cache 15.70 GB: 101.5 tok/s (9.85 ms a token), a 96.59% expert hit rate, 51.6 MB a token over the link, 1.84 ms of each token waiting for copies (19%). - Three lanes, three different prompts, same server: hit rate 91.05%, the link busy 23.8 ms of a 27.5 ms round (87%), 15.0 ms of the round waiting for copies (55%). Sources: docs/findings/ in the repo (flash-next-decode-headroom), docs/adr/0044 (experts in trellis with a K per expert) and docs/user/concepts/models-and-artifacts.md. How this video was made Motion graphics only, every figure from the measurements above. Narration: Qwen3-TTS (AI voice). Music: ACE-Step 1.5 (AI-generated). Built with HyperFrames. #LLM #MixtureOfExperts #MoE
Recent news
MORE>>-
 CRYPTO_BEN
2026-11-23 06:53
-
 子敬.轮回珠宝
2026-11-23 06:53
-
 kumis patiler
2026-11-23 06:53
-
 Ha Ms
2026-11-23 06:53
-
 CryptoMetric
2026-11-23 06:53
-
 劇翻天 Drama Go
2026-11-22 16:36
-
 CryptoMason
2026-11-22 16:22
-
 Lý Tử Ly
2026-11-22 14:42
-
 Pidoku
2026-11-22 14:15
Selected Topics
-
- Dogecoin whale activity
- Get the latest insights into Dogecoin whale activities with our comprehensive analysis. Discover trends, patterns, and the impact of these whales on the Dogecoin market. Stay informed with our expert analysis and stay ahead in your cryptocurrency journey.
-
- Dogecoin Mining
- Dogecoin mining is the process of adding new blocks of transactions to the Dogecoin blockchain. Miners are rewarded with new Dogecoin for their work. This topic provides articles related to Dogecoin mining, including how to mine Dogecoin, the best mining hardware and software, and the profitability of Dogecoin mining.
-
- Spacex Starship Launch
- This topic provides articles related to SpaceX Starship launches, including launch dates, mission details, and launch status. Stay up to date on the latest SpaceX Starship launches with this informative and comprehensive resource.
-
- King of Memes: Dogecoin
- This topic provides articles related to the most popular memes, including "The King of Memes: Dogecoin." Memecoin has become a dominant player in the crypto space. These digital assets are popular for a variety of reasons. They drive the most innovative aspects of blockchain.
Selected Articles
More>>- 1 Arctic Pablo Coin (APC): Uncovering Earth's Mysteries, One Presale at a Time
- 2 New Highs For Dogecoin, Pepe and Shiba Inu In 2025 But This Crypto May Steal The Show With 10,000% Gains
- 3 Meme Coin Doge Uprising (DUP) Could 100x After President Donald Trump Announces Crypto Strategic Reserve
- 4 Dogecoin (DOGE) Price Prediction: Could Meme Coin Hit $10 by the End of 2025?
- 5 Cardano's Charles Hoskinson Has Made Some Notable Remarks About Bitcoin and Dogecoin
- 6 Cloud Mining Craze: Bitcoin, Dogecoin, and the Quest for Passive Crypto Income
- 7 Grayscale, Dogecoin, and the ETF Debut: A New Era for Meme Coins?
- 8 Rexas Finance (RXS) Could Surge 10x by 2025, Outpacing Pepe (PEPE)
- 9 Bitcoin Trader Who Made $30 Million On DOGE Predicts 6,000% Surge For This $0.0000002 AI Token – Get 80% Bonus Tokens
- 10 Dogecoin (DOGE) Price Prediction: Meme Coin Could Rally To $0.27 As It Closes Above Pre-Halving Highs
Select Currency

US Dollar
USD

Chinese Yuan
CNY

Japanese Yen
JPY
South Korean Won
KRW

New Taiwan Dollar
TWD

Canadian Dollar
CAD

Euro
EUR

Pound Sterling
GBP

Danish Krone
DKK

Hong Kong Dollar
HKD

Australian Dollar
AUD

Brazilian Real
BRL

Swiss Franc
CHF

Chilean Peso
CLP

Czech Koruna KČ
CZK

Singapore Dollar
SGD
Indian Rupee
INR
Saudi Riyal
SAR
Vietnamese Dong
VND

Thai Baht
THB
Select Currency
-
US Dollar
USD-$

-
Chinese Yuan
CNY-¥
-
Japanese Yen
JPY-¥
-
South Korean Won
KRW -₩
-
New Taiwan Dollar
TWD-NT$
-
Canadian Dollar
CAD-$
-
Euro
EUR - €
-
Pound Sterling
GBP-£
-
Danish Krone
DKK-KR
-
Hong Kong Dollar
HKD- $
-
Australian Dollar
AUD-$
-
Brazilian Real
BRL -R$
-
Swiss Franc
CHF -FR
-
Chilean Peso
CLP-$
-
Czech Koruna KČ
CZK -KČ
-
Singapore Dollar
SGD-S$
-
Indian Rupee
INR -₹
-
Saudi Riyal
SAR -SAR
-
Vietnamese Dong
VND-₫
-
Thai Baht
THB -฿